 新川サーバー | エンタープライズ サーバー ハードウェア サプライヤー
训练时间的算账:为什么 8-GPU 节点赢在墙钟
LLM 训练的成本可以简化成一道题:同样 1,000 GPU 小时的工作量,用 4 台双卡服务器跑和用 1 台 8 卡服务器跑,墙钟时间差多少?答案不止 4 倍——因为 GPU 间通信是训练的关键路径。PowerEdge XE9680 的 8 颗 GPU 通过 NVLink(NVIDIA)或 Infinity Fabric(AMD)全互联,模型并行(TP/PP)的通信延迟比跨节点走网络低一个数量级。8 卡节点内部通信,4 台双卡节点要跨 100GbE/IB 网络跑同样数据——墙钟时间、能耗、网络带宽全部翻倍。
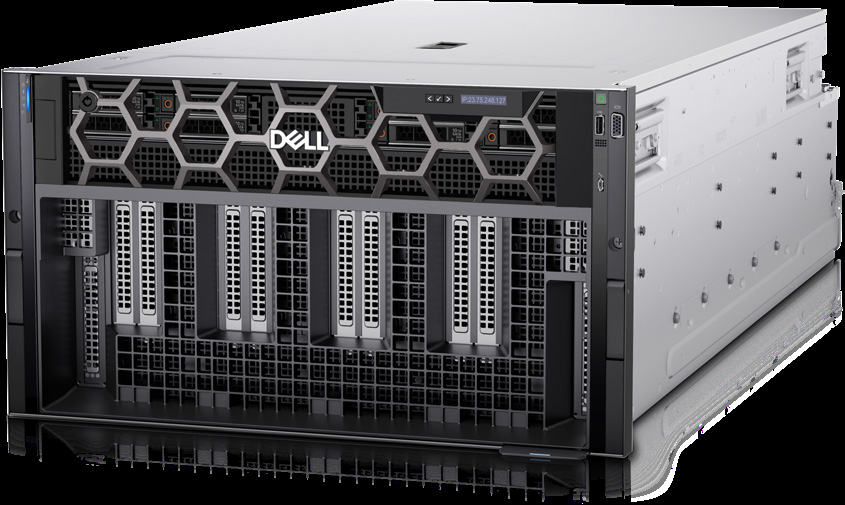
这就是 XE9680 存在的理由:Dell 首款 8 路 GPU 服务器,专为生成式 AI、ML/DL 训练和 HPC 打造,支持大语言模型、推荐引擎、分子动力学和基因组测序。
コア仕様
| 属性 | 仕様 |
|---|---|
| フォームファクタ | 6Uラックサーバー |
| プロセッサ | 2 x 5th Gen Intel Xeon Scalable (64 コア) また 2 x 4th Gen (56 コア) |
| メモリー | 32 x DDR5 RDIMM スロット, まで 4 結核, 5600 MT/秒 (5第 3 世代) / 4800 MT/秒 (4第 3 世代) |
| GPUオプション | 8 x H100 80GB 700W / 8 x H200 141GB 700W / 8 x H20 96GB 500W (all NVLink), 8 x MI300X 192GB 750W (Infinity Fabric), 8 x Gaudi 3 128GB 900W (RoCE) |
| Shared GPU memory | まで 1.5 TB coherent (MI300X config) |
| ドライブベイ | まで 8 x 2.5-inch NVMe/SAS/SATA (122.88 結核) また 16 × E3.S NVMe |
| ブート | ボス-N1: ハードウェアRAID 1, 2 × M.2 NVMe |
| PCIe | まで 10 x Gen5 x16 slots (8 with Gaudi 3) |
| 通信網 | 2 x 1GbE embedded + 1 ×OCP 3.0 (x8); 6 x 800GbE OSFP with Gaudi 3 |
| 電源ユニット | 3200Wチタン (277VAC/260-400VDC) or 2800W Titanium, hot-swap redundant |
| 管理 | iDRAC9, iDRAC ダイレクト, Redfish RESTful API, オープンマネージエンタープライズ |
| 寸法 / 重さ | 263.2 バツ 482 バツ 1008.77 んん (ベゼル付き); まで 114.05 kg |
The GPU Choice: Five Accelerators, One Chassis
The XE9680 is unusual in accepting every major accelerator generation:
| Accelerator | メモリー | 力 | Fabric |
|---|---|---|---|
| NVIDIA H100 SXM5 | 80 GB | 700 W | NVリンク |
| NVIDIA H200 SXM5 | 141 GB | 700 W | NVリンク |
| NVIDIA H20 SXM5 | 96 GB | 500 W | NVリンク |
| AMD MI300X OAM | 192 GB | 750 W | Infinity Fabric |
| インテル ガウディ 3 OAM | 128 GB | 900 W | Ethernet RoCE (embedded 800GbE) |
One chassis, five GPU generations – the platform choice follows the model and the supply line, not a lock-in.

Storage and Expansion for Training Data
まで 8 x 2.5-inch NVMe/SAS/SATA drives (122.88 結核) また 16 x E3.S NVMe drives feed the training pipeline without a separate storage hop; BOSS-N1 handles boot duty in hardware RAID 1. Ten front-facing PCIe Gen5 x16 slots take HBAs, high-speed NICs or NVMe-of-F targets, and the OCP 3.0 スロット (x8) adds a 100/400GbE card for multi-node scaling. PERC H965i covers SAS RAID (not supported with Gaudi 3).
安全 & 管理
安全. シリコンの信頼のルート, セキュアブート, 暗号的に署名されたファームウェア, 安全なコンポーネントの検証, 安全な消去, システムのロックダウン (iDRAC9 エンタープライズ/データセンター), Data at Rest Encryption via SEDs, and TPM 2.0 (FIPS/CC-TCG 認定, China variant).
管理. iDRAC9 with dedicated port, HTML5仮想コンソール, virtual media and Redfish; OpenManage Enterprise with Power Manager, Service and Update plugins, plus integrations for Ansible, Terraform, ServiceNow and BMC TrueSight – the same fleet plane as every other PowerEdge.
力, 冷却 & 物理的な
- 電源ユニット: 3200Wチタン (277 VACまたは 260-400 VDC, US/Canada) or 2800W Titanium (200-240 VAC / 240 VDC), hot-swap redundant.
- 冷却: Air-cooled with up to 6 HPR Gold fans in the mid tray + まで 10 on the rear (12 with Gaudi 3) – designed for 700-900W accelerators.
- 物理的な: 263.2 バツ 482 バツ 1008.77 んん (ベゼル付き), まで 114.05 kg – plan floor load and rail ratings.
OS & ソフトウェア
正規 Ubuntu サーバー LTS, レッドハット エンタープライズ リナックス, SUSE Linux Enterprise Server および VMware ESXi; Dell Validated Designs for Generative AI cover the reference workflows end to end.
購入に関するよくある質問
- Which GPU? H200 (141GB) for the largest models; H100/H20 for cost tiers; MI300X for AMD estates; Gaudi 3 for Ethernet-only fabrics.
- トレーニングまたは推論? Built for training/HPC; inference workloads may scale better on L40S-class nodes – see our L40S.
- Multi-node? 100/400GbE via OCP 3.0; Gaudi 3 builds embed 6 x 800GbE OSFP.
- 重さ? まで 114.05 kg fully loaded – rack planning required.
- リモート管理? iDRAC9 + オープンマネージ, identical to the rest of the fleet.
Scaling your AI estate? The XE9680 anchors the training tier; xFusion 5885H V7 covers 4-socket compute. As an authorized Dell partner we offer competitive pricing, カスタム構成, 3-年間保証と世界各地への発送 – お問い合わせ for an AI infrastructure quote.

注記: GPU availability and lead times vary by region and accelerator – confirm current allocation with our team before planning the build.